Written by Trivender Singh
Co-Founder at TechniqCo | GEO & AEO Expert specializing in Generative Engine Optimization, Answer Engine Optimization, AI Search Visibility, Technical SEO & Business Growth Scaling.
Jev AI is the flagship artificial intelligence model developed by TypeSafe AI, founded by former OpenAI researcher Diogo Almeida with 40 million dollars in seed funding. Unlike traditional conversational Large Language Models (LLMs) like ChatGPT that generate natural language prose, Jev is a specialized System One decision engine. It evaluates unstructured program states and delivers typed, calibrated decisions (choices, scores, and yes/no probabilities) directly into software in 70 to 500 milliseconds, operating 40 to 200 times faster than chat models with zero type hallucinations.
For the past four years, the generative artificial intelligence industry has been obsessed with conversational chat interfaces. Whenever developers needed software to make a judgment, whether categorizing a customer support ticket, scoring a sales lead, or checking content for brand safety, they were forced to prompt a massive conversational LLM like GPT-4 or Claude.
The problem is that traditional LLMs are designed to talk to human beings, not machines. When your application simply needs to know whether an inbound customer is angry or which department should handle an email, buying an entire conversational essay from a 70-billion-parameter model is slow, expensive, and prone to formatting errors. Parsing freeform prose back into structured code requires complex regex hacks, fragile JSON prompts, and multiple retry loops.
Launched in September 2026, Jev AI by TypeSafe AI completely redesigns this architecture. Instead of generating conversational text, Jev functions as a deterministic, sub-second decision layer for software. Below is the complete technical breakdown of Jev AI, including its architectural origins, the three core primitives, playground user interface, real-world enterprise use cases, API integration, and full pricing model.
The Architectural Shift: System One vs. System Two AI
To understand why Jev represents a major milestone in machine intelligence, one must examine the cognitive framework that inspired its design: psychologist Daniel Kahneman’s distinction between System One and System Two thinking.
- System Two (Slow, Deliberate, Conversational): This represents traditional generative models like ChatGPT, Claude 3.5 Sonnet, and Google Gemini. They synthesize knowledge, write complex code, debate philosophical points, and produce step-by-step reasoning. However, they take 2 to 10 seconds to generate an answer, consume massive computing power, and cost several cents per response.
- System One (Fast, Reflexive, Calibrated): This represents Jev. When an experienced driver spots a red traffic light, they do not write an essay on automotive physics; they instantly press the brake. Jev is trained specifically for this reflex-style judgment. It evaluates complex input states against narrow questions and delivers typed, calibrated decisions in 70 to 500 milliseconds.
TypeSafe AI was founded by Diogo Almeida (co-inventor of Reinforcement Learning from Human Feedback and an early core researcher behind ChatGPT at OpenAI) alongside Erik Gafni and Sasha Sheng. Emerging from stealth with a 40 million dollar funding round led by DCVC, the team trained Jev using a proprietary technique called Reinforcement Learning for Calibrated Decisions (RLCD).
Because Jev is trained strictly to output structured mathematical distributions rather than freeform text tokens, it is mathematically incapable of generating syntax hallucinations or invalid data types.
The Three Decision Primitives of Jev AI
Every judgment in Jev AI is built on three foundational, strongly-typed question primitives. A single API request can submit up to eight independent questions against a single state, evaluating all of them simultaneously in one lightning-fast network round trip:
| Primitive | Data Type | Function and Output Structure | Ideal Use Case |
|---|---|---|---|
| Choice | Categorical Enum | Picks the winning key from up to 255 defined options. Returns the selected label, full probability distribution across all choices, and overall confidence score. | Department routing, topic classification, hook style tagging, language detection |
| Score | Ordinal Range | Places input text onto an ordered spectrum of 2 to 10 customizable levels. Returns an exact decimal score and level probabilities. | Urgency scoring, customer frustration levels, lead fit rating, code review risk |
| Noul | Calibrated Boolean | Evaluates a binary yes or no question, returning a calibrated probability value strictly bounded between 0.0 and 1.0. | Spam filters, escalation gates, tool-execution safety checks, prompt injection detection |
The Jev AI Playground and User Interface
For developers, product managers, and growth teams wanting to evaluate Jev without writing code, several web platforms provide instant browser access:
- Official TypeSafe Platform (
jevtypesafeai.com): Features the primary web playground where users can paste raw unstructured text (the “state”) on the left, configure typed question blocks, and trigger evaluations against the liveapi.typesafe.ai/v1/systemoneendpoint. - Jev AI Web Pro (
jev-ai.pro): An independent playground and workspace offering 5 free test runs, batch CSV processing, and comparison teardowns against models like djev and SemIf. - Jev Community Hub (
jevai.org): An open ecosystem hub providing pre-built prompt templates, community-tested playbooks, open-source plugins, and interactive browser widgets.
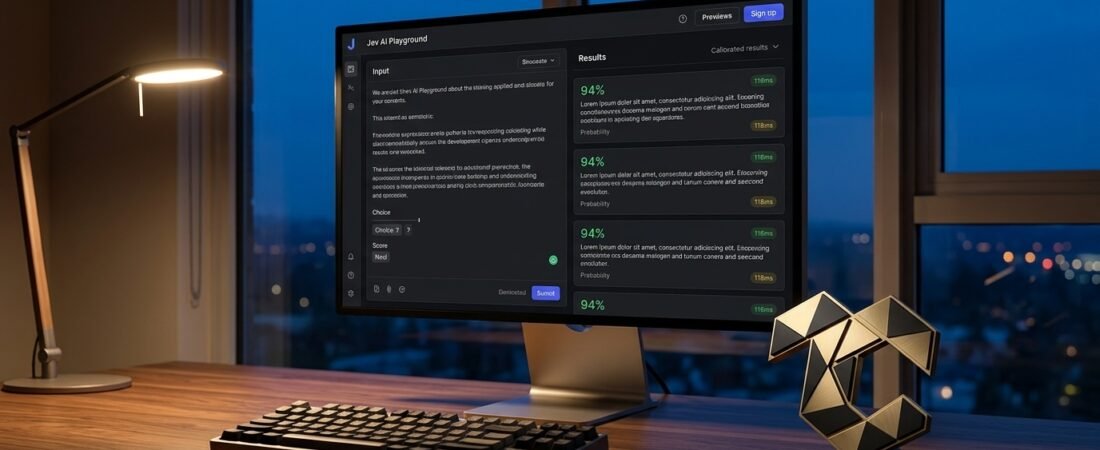
The playground interface is divided into four distinct workflow panels:
- 1. State Input Box: A clean text area supporting up to 32 KiB of context. This can be raw text, social media posts, customer support emails, or serialized JSON objects.
- 2. Question Builder: Allows users to add up to 8 questions per run, choosing between Choice, Score, or Noul types, setting custom criteria and boundary descriptions.
- 3. Real-Time Results Inspector: Displays the winning decision, the exact probability percentage (for example,
billing: 94%), confidence rating, total elapsed latency in milliseconds, and token usage metrics. - 4. One-Click API Request Preview: Shows the exact JSON payload sent over the wire, allowing software engineers to copy-paste production-ready code directly into Python, Node.js, or Go applications.
Real-World Benchmarks and Enterprise Use Cases
Because Jev evaluates decisions without generating conversational tokens, the performance and financial economics are dramatic compared to frontier chat models:
Case 1: Viral Social Media Analysis (100,000 Posts)
The Task: Classify 100,000 viral posts on X across hook type, evidence strength, curiosity loops, and virality potential.
Frontier Chat Model (GPT-4o / Claude): Processed only 214 posts in the same timeframe and projected a total model cost of approximately 458 dollars.
Jev AI Execution: Evaluated all 100,000 posts in 20.4 seconds for a total cost of 0.67 dollars (over 680 times cheaper per item).
Case 2: SEO Internal Link Architecture (586 Pages)
The Task: Ingest 586 published website URLs, evaluate topical relevance pairs, and establish semantic internal link connections.
Jev AI Execution: Rebuilt the entire site architecture in 45.1 seconds for 0.21 dollars, accurately placing 584 contextual links and leaving 139 unrelated pages untouched.
Case 3: Ad Creative Teardown (724 Live Ads)
The Task: Break down 724 active Meta and Google ads from 37 commercial brands into awareness stages, offer types, and friction scores.
Jev AI Execution: Completed the full taxonomy tagging in approximately 40 seconds for 0.09 dollars, converting raw ads directly into structured analytical datasets.
Case 4: Context Compaction for Claude Code
The Task: During extensive multi-hour coding sessions, agent context windows fill with stale terminal outputs and tool logs. Traditional summarizers rewrite code and introduce lossy mistakes.
Jev AI Solution (fast-jev-compaction): Jev evaluates individual tool results on a binary keep-or-drop decision, stripping stale logs while preserving critical code verbatim.
Jev AI vs. Traditional LLMs: A Structural Comparison
| Feature Metric | Traditional LLMs (GPT-4o, Claude 3.5) | Jev AI (TypeSafe System One) |
|---|---|---|
| Primary Objective | Conversational text and code generation | Fast, typed decisions for software systems |
| Response Latency | 1,500 to 8,000 milliseconds | 70 to 500 milliseconds (40 to 200x faster) |
| Output Format | Unstructured prose (requires JSON parsing) | Calibrated choices, scores, and probabilities |
| Input Token Pricing | 2.50 to 5.00 dollars per million tokens | 0.25 to 0.42 dollars per million tokens |
| Output Token Pricing | 10.00 to 15.00 dollars per million tokens | 100% Free (Zero output token charges) |
| Hallucination Risk | Moderate to high (can invent text and keys) | Zero (responses are bound by schema types) |
| Confidence Scoring | Uncalibrated verbal self-assessment | Mathematically calibrated probability distributions |
How to Code with Jev AI: Python Integration
Integrating Jev into production microservices is straightforward. Below is an example of classifying and routing customer support messages using the official Python SDK:
import typesafe

# Initialize the TypeSafe client
client = typesafe.Client(api_key="jev_live_secret_key")

support_ticket = """
Subject: Charged twice again!!
This is the SECOND month in a row I have been billed twice for the Enterprise plan.
I emailed last week and received no response. If this is not refunded today,
I am cancelling our account and filing a payment dispute.
"""

# Submit program state and typed questions
decision = client.decide(
    model="jev-1",
    state=support_ticket,
    questions={
        "category": ["billing", "bug", "account", "feature_request"],
        "urgency": ("score", 1, 4),
        "needs_human_escalation": bool,
    }
)

# Output structure returned in ~110ms:
# {
#   "category": ("billing", p=0.98),
#   "urgency": (4, confidence=0.95),
#   "needs_human_escalation": (True, p=0.99)
# }

if decision["needs_human_escalation"].value:
    print(f"Priority Alert: Route to Executive Support queue with urgency {decision['urgency'].value}")
Jev AI Pricing and Token Economics
The cost structure of Jev AI disrupts traditional software economics by making output tokens completely free:
- Input Token Rate: Charged at 0.42 dollars per million input tokens (with volume tiers dropping to 0.25 dollars per million on enterprise agreements).
- Output Token Rate: Zero dollars. Because Jev returns mathematical choices rather than generative text strings, you never pay for output token generation.
- Cost Per Decision: Benchmark tests indicate the average cost per complete decision run is approximately 0.0004 dollars (four hundredths of a single cent).
- Free Tier and Developer Credits: New accounts receive 5 free runs immediately on the playground. Community platforms like
jev-ai.proandjevai.orgprovide free daily testing allotments without requiring credit card registration.
Frequently Asked Questions
Can Jev AI write essays, creative copy, or blog posts?
No. Jev is intentionally designed without text generation capabilities. It cannot write stories, draft emails, or hold natural language conversations. It is built strictly to evaluate text states and return structured data types (enums, scores, and probabilities) for software backends.
Is Jev AI an open-source model?
The core Jev model weights are proprietary and hosted directly on TypeSafe AI cloud infrastructure. However, the ecosystem surrounding Jev, including the Python SDK, LangChain community integrations, Model Context Protocol (MCP) servers, and plugins like fast-jev-compaction, are fully open source on GitHub.
Does Jev support images, video, or audio files?
Jev accepts text only, including plain strings, serialized JSON objects, or string arrays. Non-text assets must be transcribed, extracted, or OCR-processed into text before being passed into the state parameter. A multimodal version called Jev-Omni is currently undergoing experimental testing.
How does Jev guarantee zero hallucinations?
In traditional LLMs, hallucinations occur during autoregressive token sampling when the model attempts to guess the next word in a sentence. Jev does not sample text words. Because the response schema is hard-locked by the typed question structure, the model is physically constrained to output calibrated probabilities across predefined options.
What languages are supported by Jev AI?
English is Jev’s primary and most calibrated language. While it can process multilingual inputs in languages including French, German, Spanish, and Mandarin, classification confidence is highest on English-language context.
How do developers access the Jev AI API?
Developers can register for early API credentials directly at jevtypesafeai.com, connect via modern API gateways like Cloudflare and Vercel AI Gateway, or test interactive prototypes on community platforms like jev-ai.pro and jevai.org.
What does Jev mean for the future of AI agents?
Autonomous AI agents spend up to 70% of their operational cycles executing micro-decisions: determining which tool to call, verifying file edit safety, or checking whether an execution loop is complete. Using slow frontier models for these checks creates unacceptable latency and cost. Jev provides the missing sub-second decision layer, allowing agent frameworks to run complex workflows with unprecedented speed.
How does TechniqCo leverage modern AI models like Jev?
TechniqCo integrates cutting-edge decision models into client growth architectures. From automated lead qualification and real-time ad bidding to programmatic Generative Engine Optimization (GEO), we help ambitious companies build intelligent systems that scale revenue efficiently.
Build Next-Generation AI Growth Systems with TechniqCo
Whether you are building autonomous marketing agents, optimizing your brand for AI search citations, or scaling performance advertising funnels, TechniqCo delivers the technical engineering and strategic expertise to keep your business ahead of the curve. Schedule a strategic consultation with our founding team today.
Schedule an AI Strategy Session →Related posts:
 Technical SEO for AI Crawlers 2026: Sitemaps, Schema, and Robots Strategies That Work
 ChatGPT vs. Claude for SEO in 2026: Which AI Wins at Each Stage of the Workflow?
 The ChatGPT Ads Playbook for Indian Brands: Tracking, Attribution, and the GEO Formula
 The Ultimate On-Page SEO Checklist 2026: 47 Points to Rank #1 on Google
 ChatGPT Ads Are Now in India: What Businesses Need to Know About the New Advertiser
 How to Do a Website Audit: A Complete Step-by-Step Guide for 2026